publications
A selected list with short digests. An asterisk (*) denotes equal contribution; see my Google Scholar for the full list.
2026
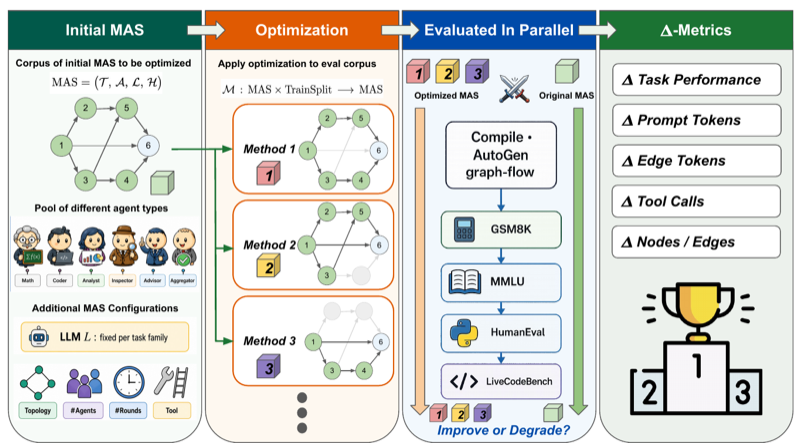
- Rethinking the Evaluation of Efficiency Methods for Multi-Agent SystemsOutstanding Paper AwardIn EMNLP, Oral , 2026TL;DREvaluationMulti-AgentEfficiency
Many methods claim to make LLM multi-agent systems (MAS) cheaper by pruning agents or communication edges – but do the gains really come from the method? Reported improvements are often measured under method-specific prompts and starting topologies, and many appear in settings where a single agent or even random pruning already does well. We introduce a controlled, MAS-demanding diagnostic benchmark that evaluates representative efficiency methods under shared model, agent, and runtime settings across topology, scale, depth, and tool use, and find that many reported gains are setup-dependent – arising from structural collapse, disabled tool pathways, or easy pruning rather than genuine efficiency improvements.
- Preprint
 BellowsKV: One Latent for Many Layers, Expanded on DemandarXiv preprint arXiv:2610.35023, 2026TL;DREfficiencyKV CacheCompression
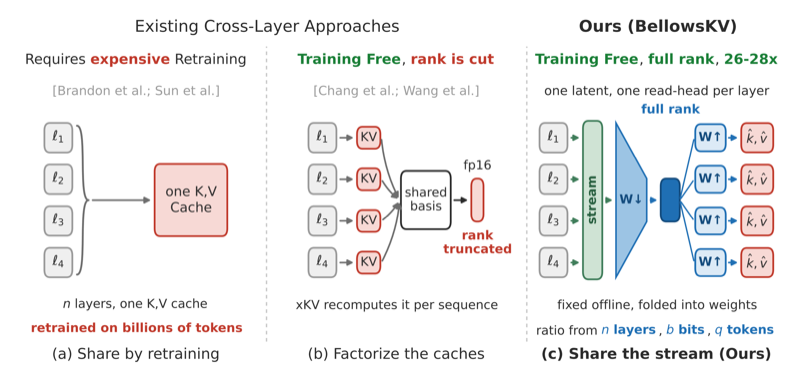
Every transformer layer keeps its own KV cache and re-reads it at each generation step, so for long-context serving the cache, not the weights, becomes the bottleneck. Compressing inside a single layer – quantizing entries, cutting the channel dimension, evicting tokens – loses substantial accuracy at high ratios, and existing cross-layer sharing degrades sharply too. We find that adjacent layers’ KV representations differ considerably while their input hidden states are nearly identical, and that under a fixed budget shrinking a shared latent’s dimension costs far more accuracy than quantizing it. BellowsKV is training-free: it maps the hidden states of n adjacent layers to a single full-dimension latent per token, from which each layer reads its own keys and values through a layer-specific projection, then compresses that latent by precision (no dominant outlier channels, so low precision is nearly lossless) or by one eviction decision per block (the layers rank token importance very similarly). Across Llama-3.1-8B, Mistral-7B and Qwen2.5-7B it retains about 99% of full-cache accuracy at 3.6x compression and 97–98% at 13–14x, where the strongest existing cross-layer method retains at most 84% at 16x.
- Preprint
 SPECTRA: Pushing the KV Cache Beyond the 2-Bit Cliff via Spectral Transform CodingarXiv preprint arXiv:2608.07915, 2026TL;DREfficiencyQuantizationLong Context
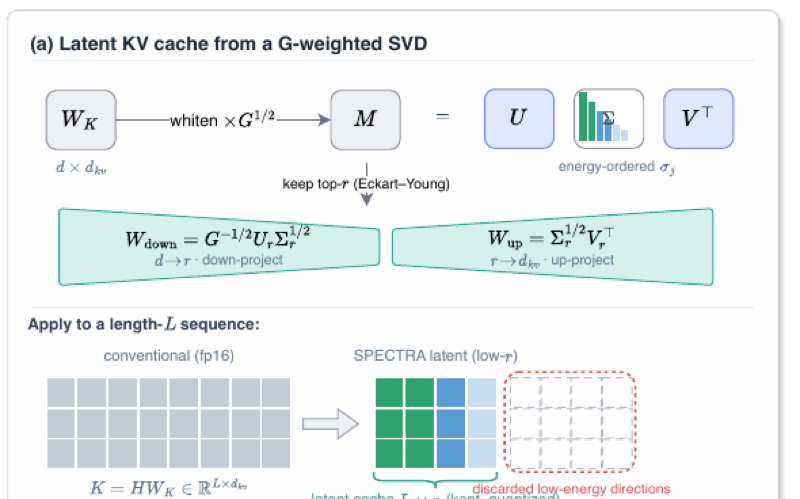
As LLMs read longer inputs, inference memory is dominated by the KV cache, and the usual fix – quantizing every stored value to the same low precision – stalls at a 2-bit cliff, where four levels are too few for the cache’s outlier-heavy values. Spending more bits on the channels that matter would help, but the raw cache offers no handle: its channels are strongly correlated, so none stands out. We show the handle appears once the cache is rotated into a coordinate system computed from its own statistics – there a small fraction of channels carries almost all the information. SPECTRA is a training-free, drop-in codec built on this observation: on Llama-3.1-8B and Qwen2.5-7B long-context benchmarks it is near-lossless at 4x compression, competitive at 8x where uniform quantization has collapsed, and reaches up to 12x.
- Under Review
 Recognizing and Restructuring Latent Experts for Large Language Model CompressionUnder review, 2026TL;DREfficiencyCompressionMoE
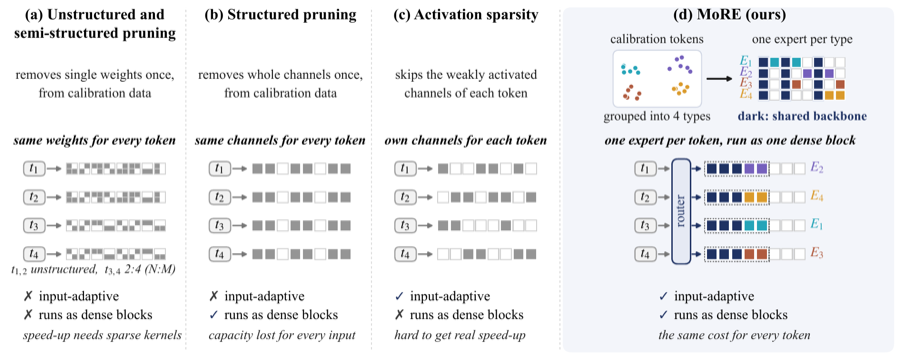
Static compression like pruning permanently removes parameters deemed globally unimportant – but in LLMs, importance is highly input- and task-dependent, so static removal is brittle under distribution shift. Inspired by conditional computation in Mixture-of-Experts, MoRE (Mixture-of-Recognized-Experts) is a training-free paradigm that turns static redundancy in pretrained Transformers into input-dependent sparse computation. We find that pretrained MLP layers have a hybrid structure – a shared backbone that is always active plus input-dependent residual components that enable specialization – and MoRE exploits it through training-free routing, activating different subsets of pretrained parameters per input without modifying any weights. Across model families and benchmarks, MoRE matches or beats structured pruning on accuracy–efficiency trade-offs while staying robust under distribution shift and knowledge-intensive QA.
- Preprint
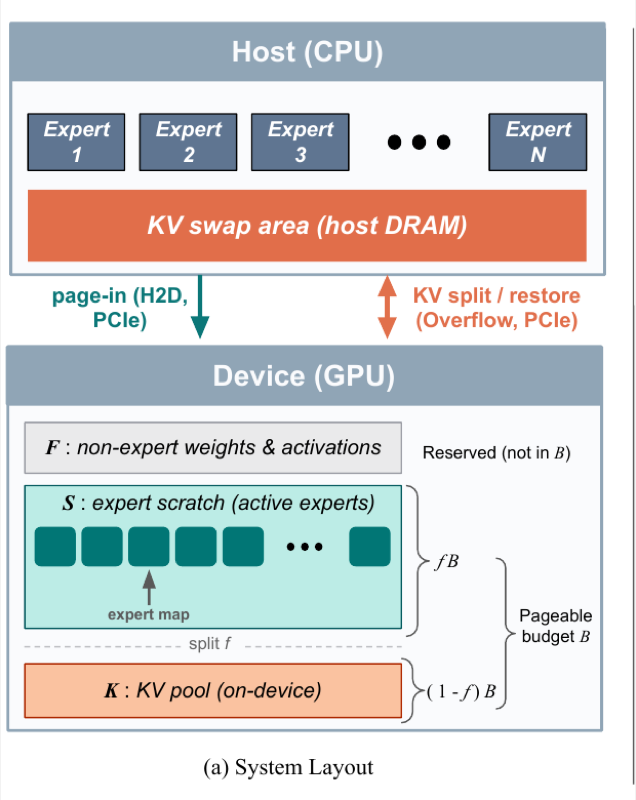 WiSP: A Working-Set View of Mixture-of-Experts Serving on Extremely Low-Resource HardwarePreprint (work in progress), 2026TL;DREfficiencySystemsMoE
Mixture-of-Experts models put most of their parameters in experts, yet only a few fire per token – and on commodity GPUs the usual layer-level CPU offload streams every expert across PCIe on each forward pass, throwing away MoE’s sparsity. WiSP treats low-resource MoE serving as a GPU working-set problem, paging in only the experts a workload actually reuses, and reaches up to 1.95x the decode throughput of static offload at the same memory budget with byte-identical outputs. A companion allocator, MV-WSA, splits VRAM between experts and the KV cache by equalizing marginal latency benefit per byte.
2025
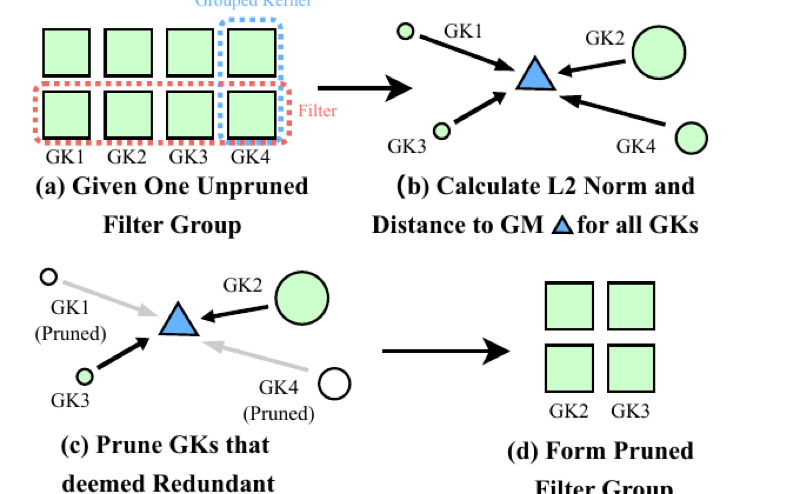
- Flexible Group Count Enables Hassle-Free Structured PruningIn IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025TL;DREfficiencyPruning
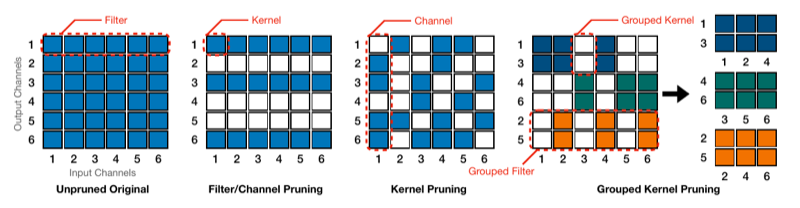
Structured (grouped-kernel) pruning normally forces you to pre-commit to a rigid group count, making it painful to reuse across architectures. We make the group count flexible and hassle-free, so a single procedure prunes convolutional models cleanly while preserving the dense, hardware-friendly structure that delivers real speedups.
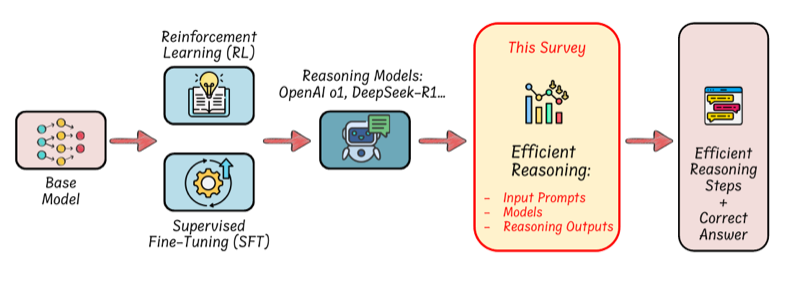
- Stop Overthinking: A Survey on Efficient Reasoning for Large Language ModelsTransactions on Machine Learning Research (TMLR), 2025TL;DRSurveyEfficiencyLLM
Long chain-of-thought reasoning boosts accuracy but burns a lot of test-time compute – the “overthinking” phenomenon, where a model may spend hundreds of tokens on a trivial question. This is the first structured survey of efficient reasoning for LLMs, organizing the fast-growing literature into model-, output-, and prompt-level directions. It has been widely covered by AI media (e.g., 新智元, 科技行者, and Towards AI) and reshared across X and RED, with citations climbing fast.
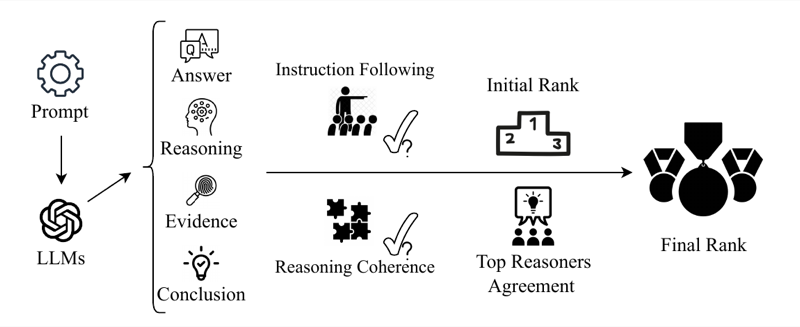
- Redefining Language Model Evaluation with Ground-Truth-Free Ranking FrameworksIn Findings of the Association for Computational Linguistics (ACL Findings), 2025TL;DREvaluationLLM
Evaluating LLMs usually leans on ground-truth labels that are expensive and often unavailable. We rank models without any ground truth, using a reasoning-consistency framework that yields reliable, label-free rankings well correlated with traditional benchmarks.
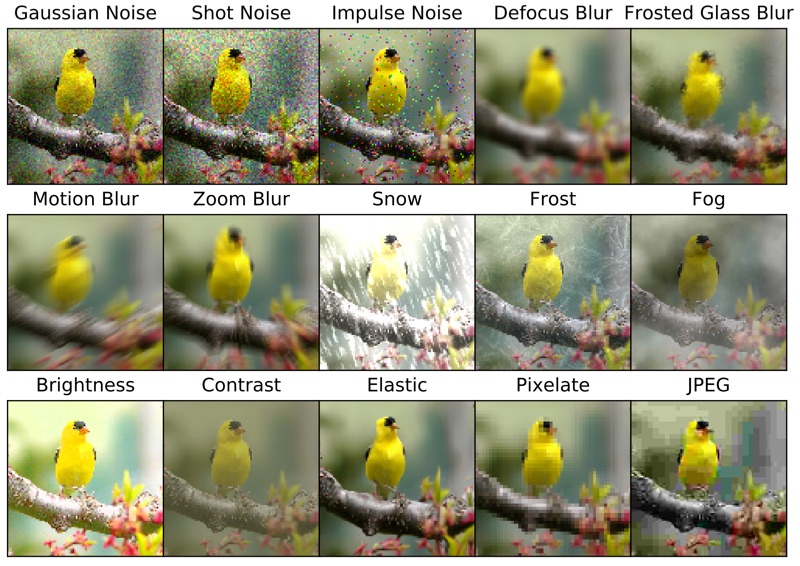
- In-Progress: Structured Pruning in the Wild: Benchmarking Practical Robustness Under Real-World CorruptionsIn IEEE Security and Privacy Workshops (SPW), 2025TL;DRRobustnessEvaluation
Structured-pruned models often look fine on clean data but degrade under real-world corruptions. We benchmark the practical robustness of pruned models under realistic corruptions, surfacing when and how pruning quietly trades away reliability.
- arXiv
 The Science of Evaluating Foundation ModelsarXiv preprint arXiv:2502.09670, 2025TL;DREvaluation
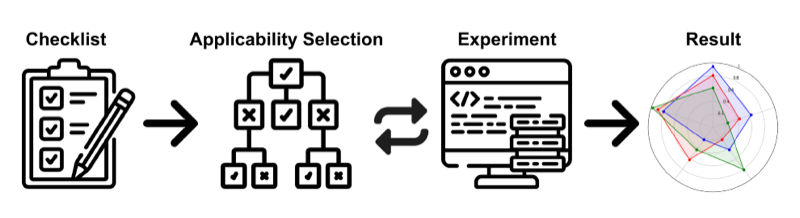
Foundation-model evaluation is fragmented and frequently ad hoc. This work lays out principles and a structured framework for evaluating foundation models rigorously – what to measure, how, and why – toward assessments that are trustworthy and comparable.
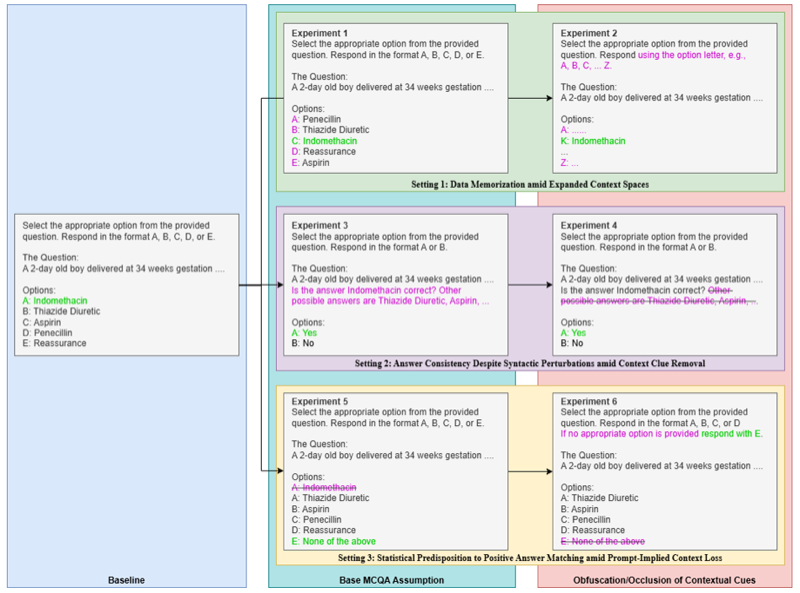
- Context Matching is not Reasoning: Assessing Generalized Evaluation of Generative Language Models in Clinical Settingsnpj Digital Medicine, 2025TL;DREvaluationHealthcare
Generative LLMs can appear competent in clinical QA by matching surface context rather than genuinely reasoning. Through a generalized clinical evaluation, we show that strong benchmark numbers can mask a real lack of reasoning in medical settings.
2024
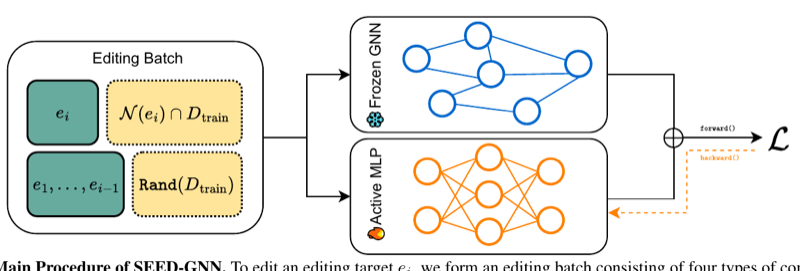
- GNNs Also Deserve Editing, and They Need It More Than OnceIn International Conference on Machine Learning (ICML), 2024TL;DRRobustnessGraphs
Model editing – fixing mistakes postmortem – is common everywhere except graphs, which are theoretically unfriendly to edits. We trace the root cause to over-accommodation of editing targets and present the first graph-editing method that lives up to real-life scrutiny of sequential edits.
2023
- One Less Reason for Filter Pruning: Gaining Free Adversarial Robustness with Structured Grouped Kernel PruningIn Advances in Neural Information Processing Systems (NeurIPS), 2023TL;DREfficiencyRobustness
Pruned convolutional models can match clean accuracy yet collapse under perturbed inputs. We fix this essentially for free with a theoretically motivated grouped-kernel-pruning procedure that leverages kernel smoothness – a property known to promote frequency robustness – at no extra cost.